
For the taskWrite in Slovak
sk-bench – a benchmark for evaluating generative language models (LLMs) in Slovak
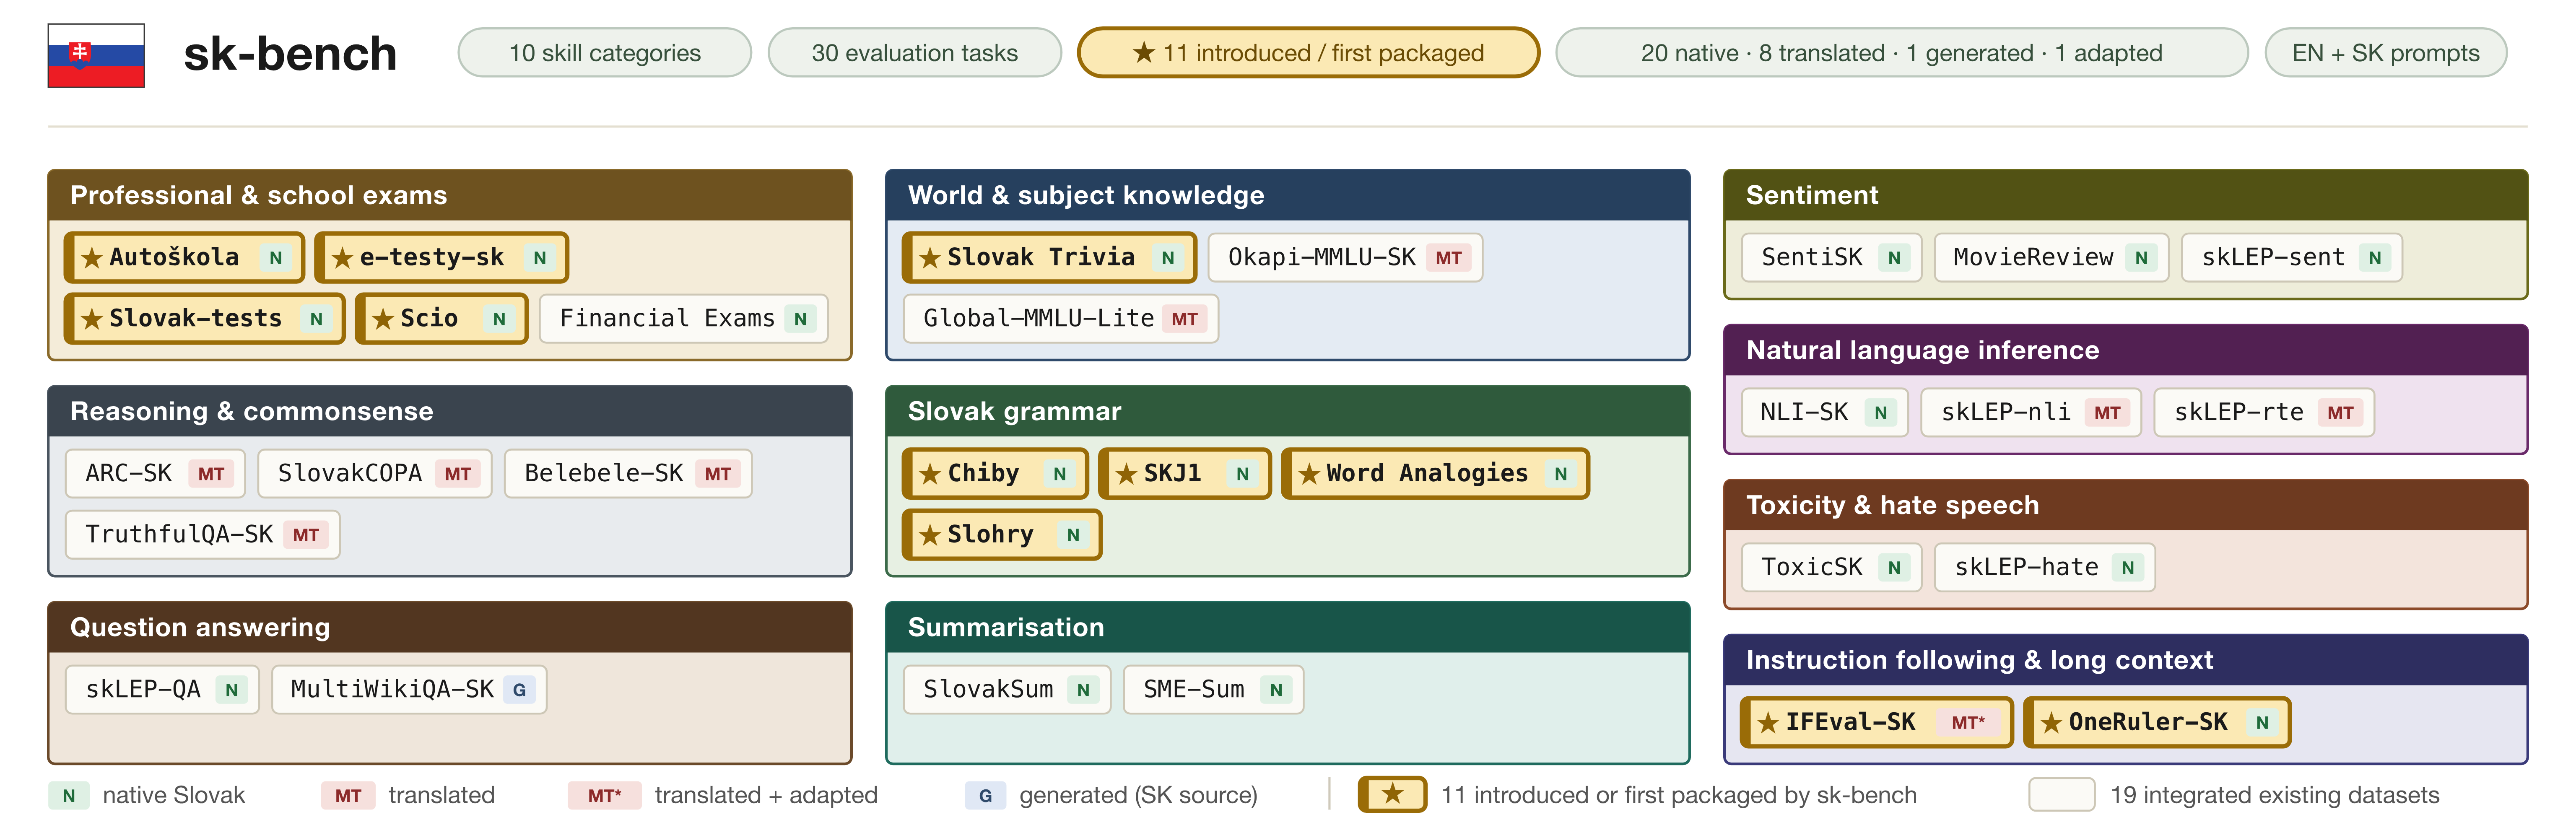
sk-bench measures how well large language models handle Slovak. It consists of 30 datasets from ten domains. Most of the data was originally created in Slovak, and translations were used only where no Slovak original existed. All models are evaluated using the same methodology and the same prompts. Results are reported as an overall score and separately for six task groups. The table below ranks multiple models by their overall score. Some of them were also evaluated with thinking mode enabled, so they appear in the table twice.
- Task
- Generative LLM Evaluation
- Metric
- Accuracy, QEM, QF1, ROUGE-L
- Modality
- Text
- Published
- October 6, 2026
- Updated
- October 9, 2026
- Models
- 79
Ranked by: Overall
- Metric direction
- higher is better
- Published
- Number of models
- 79 models
- 172.65
- 271.02
- 368.13
- 466.69
- 565.97
- 665.93
- 765.57
- 865.20
- 964.90
- 1064.66
- 1164.61
- 1264.28
- 1363.90
- 1460.53
- 1559.95
The overall score is the unweighted average of the scores of the six task groups. Each group score is the average of its task scores (× 100), with every task weighted equally. This prevents large translated datasets from having a disproportionate influence on the overall result. A higher score means a better result.
Full results table
Original benchmark results: 79 models, 8 columns. On mobile, scroll horizontally to view the table. Click an underlined column heading to sort the models in the chart above by that column’s values.
| Model | Thinking | Average per group | ||||||
|---|---|---|---|---|---|---|---|---|
| 🌐Gemini 3.1 Pro(API) | ✓ | 72.65 | 92.37 | 71.28 | 82.64 | 14.82 | 87.15 | 87.62 |
| 🌐GPT-5.5(API) | ✓ | 71.02 | 89.21 | 67.30 | 81.61 | 15.50 | 86.41 | 86.09 |
| 🌐Claude Opus 4.6(API) | ✓ | 68.13 | 87.23 | 58.60 | 83.37 | 15.36 | 80.63 | 83.59 |
| 🌐Gemini 3.1 Flash-Lite(API) | ✓ | 66.69 | 85.75 | 54.84 | 82.16 | 13.98 | 82.68 | 80.76 |
| 🌐Gemma 4 31B(31B) | ✓ | 65.97 | 83.07 | 57.56 | 81.70 | 14.65 | 83.99 | 74.89 |
| 🌐MiniMax M3(427B) | ✓ | 65.93 | 82.40 | 62.56 | 81.02 | 15.05 | 73.93 | 80.61 |
| 🌐Qwen3.6 27B(27B) | ✓ | 65.57 | 82.07 | 63.87 | 81.12 | 14.57 | 78.21 | 73.60 |
| 🌐Muse Glimmer 30B(29.6B) | ✓ | 65.20 | 82.32 | 56.38 | 77.62 | 14.23 | 84.36 | 76.30 |
| 🌐Claude Sonnet 4.6(API) | ✓ | 64.90 | 84.71 | 53.99 | 81.64 | 15.26 | 78.03 | 75.81 |
| 🌐Qwen3.6 35B-A3B(35B) | ✓ | 64.66 | 80.30 | 61.32 | 80.15 | 13.99 | 76.91 | 75.27 |
| 🌐Qwen3.8 27B(27B) | ✓ | 64.61 | 80.04 | 59.62 | 80.31 | 15.67 | 81.94 | 70.06 |
| 🌐Qwen3.5 27B(27B) | ✓ | 64.28 | 83.21 | 59.21 | 81.17 | 13.98 | 71.88 | 76.25 |
| 🌐GPT-5.4 mini(API) | ✓ | 63.90 | 78.19 | 58.04 | 78.97 | 15.16 | 80.07 | 72.96 |
| 🌐MiniMax M3(427B) | – | 60.53 | 78.27 | 56.15 | 76.45 | 15.53 | 71.69 | 65.11 |
| 🌐gpt-oss 120B(120B) | ✓ | 59.95 | 73.74 | 53.23 | 79.04 | 13.51 | 74.86 | 65.33 |
| 🌐Kimi K3(2.8T) | – | 59.38 | 84.80 | 62.90 | 82.93 | 15.45 | 33.71 | 76.51 |
| 🌐Inkling(975B) | – | 59.28 | 83.14 | 61.25 | 82.23 | 10.83 | 38.36 | 79.88 |
| 🌐GLM-5.1(754B) | – | 57.55 | 80.56 | 61.16 | 82.59 | 14.24 | 35.94 | 70.82 |
| 🌐Qwen3.5 397B-A17B(397B) | – | 57.36 | 83.41 | 55.50 | 80.56 | 14.61 | 37.80 | 72.27 |
| 🌐MiniMax M2.7(230B) | ✓ | 57.12 | 77.97 | 51.50 | 78.42 | 13.53 | 44.69 | 76.63 |
| 🌐GLM-5.2(753B) | – | 57.02 | 80.77 | 59.86 | 81.59 | 15.06 | 32.59 | 72.23 |
| 🌐Qwen3.5 9B(9B) | ✓ | 56.39 | 75.84 | 51.19 | 74.37 | 11.46 | 52.33 | 73.13 |
| 🌐Kimi K2.6(1.1T) | – | 55.68 | 80.62 | 52.73 | 77.99 | 14.71 | 31.84 | 76.20 |
| 🌐Qwen3.5 27B(27B) | – | 55.34 | 81.16 | 55.66 | 79.54 | 14.92 | 36.13 | 64.63 |
| 🌐DeepSeek V4 Flash(158B) | – | 54.96 | 78.13 | 53.43 | 72.91 | 16.35 | 33.15 | 75.77 |
| 🌐Gemma 4 31B(31B) | – | 54.25 | 78.77 | 53.13 | 82.36 | 14.40 | 30.17 | 66.70 |
| 🌐Qwen3.6 27B(27B) | – | 54.19 | 79.75 | 59.69 | 70.72 | 14.93 | 35.01 | 65.02 |
| 🌐gpt-oss 20B(20B) | ✓ | 54.07 | 67.39 | 47.58 | 76.87 | 12.97 | 62.38 | 57.21 |
| 🌐Llama 3.3 70B(70B) | – | 53.08 | 72.07 | 53.86 | 79.44 | 21.35 | 35.38 | 56.38 |
| 🌐Qwen3.6 35B-A3B(35B) | – | 52.19 | 77.17 | 55.44 | 71.84 | 14.47 | 32.77 | 61.42 |
| 🌐Nemotron 3 Super 120B A12B(120B) | – | 50.80 | 71.93 | 57.48 | 79.02 | 12.64 | 31.47 | 52.27 |
| 🌐Qwen3.8 27B(27B) | – | 50.44 | 77.54 | 55.92 | 64.28 | 14.95 | 33.15 | 56.82 |
| 🌐Qwen3.5 9B(9B) | – | 47.91 | 69.68 | 50.35 | 76.98 | 14.97 | 31.10 | 44.38 |
| 🌐Qwen3 14B(14B) | – | 47.45 | 67.07 | 49.06 | 74.30 | 16.22 | 34.08 | 43.95 |
| 🌐Granite 4.0-H Small(32B) | – | 46.99 | 67.26 | 42.43 | 71.89 | 16.43 | 33.89 | 50.03 |
| 🌐Gemma 4 12B(12B) | – | 46.64 | 69.48 | 48.67 | 79.34 | 11.80 | 23.65 | 46.87 |
| 🌐Bielik 11B(11B) | – | 46.35 | 66.55 | 47.11 | 74.64 | 12.59 | 30.35 | 46.86 |
| 🌐EuroLLM 22B(22B) | – | 45.22 | 63.87 | 41.58 | 75.00 | 15.17 | 26.44 | 49.24 |
| 🌐Mistral Large 3 675B(675B) | – | 44.95 | 77.29 | 49.27 | 65.26 | 11.75 | 20.86 | 45.28 |
| 🌐Apertus 70B(70B) | – | 44.40 | 57.52 | 43.28 | 69.71 | 13.20 | 27.93 | 54.77 |
| 🇸🇰Qwen3-SK 14B (Alpaca)(14B) | – | 43.77 | 70.03 | 45.55 | 60.16 | 14.99 | 40.97 | 30.93 |
| 🌐Granite 4.2 30B(30B) | – | 43.17 | 60.29 | 47.10 | 70.42 | 13.44 | 31.66 | 36.13 |
| 🌐EuroLLM 9B(9B) | – | 42.66 | 55.79 | 42.73 | 74.56 | 14.95 | 22.72 | 45.20 |
| 🌐DeepSeek V4 Pro(862B) | – | 42.44 | 78.44 | 46.22 | 58.80 | 14.18 | 13.22 | 43.77 |
| 🌐Aya Expanse 32B(32B) | – | 42.41 | 61.48 | 41.93 | 76.93 | 14.19 | 24.21 | 35.73 |
| 🌐Ministral 3 8B(8B) | – | 40.80 | 60.35 | 39.20 | 70.61 | 13.53 | 24.02 | 37.08 |
| 🌐Qwen3 1.7B(1.7B) | ✓ | 40.03 | 49.07 | 41.27 | 68.19 | 11.87 | 47.30 | 22.50 |
| 🌐Ministral 3 8B (R)(8B) | ✓ | 39.94 | 54.86 | 37.84 | 61.92 | 13.06 | 39.85 | 32.13 |
| 🌐Ministral 3 14B(14B) | – | 37.23 | 63.82 | 34.57 | 55.91 | 14.19 | 18.44 | 36.46 |
| 🌐Nemotron 3 Nano 30B A3B(30B) | – | 36.94 | 55.70 | 42.69 | 59.95 | 11.98 | 30.35 | 20.95 |
| 🌐Tiny-Aya Water(3.35B) | – | 36.40 | 50.48 | 34.88 | 74.29 | 10.83 | 27.56 | 20.37 |
| 🌐Command A(111B) | – | 36.23 | 64.91 | 32.38 | 38.44 | 12.39 | 26.44 | 42.84 |
| 🌐Tiny-Aya Global(3.35B) | – | 36.04 | 50.70 | 34.65 | 73.86 | 10.63 | 26.82 | 19.58 |
| 🌐Llama 3.1 8B(8B) | – | 35.14 | 47.78 | 41.43 | 60.93 | 15.35 | 19.55 | 25.81 |
| 🇸🇰Qwen3-SK 14B(14B) | – | 33.51 | 43.42 | 23.90 | 43.68 | 11.57 | 27.75 | 50.76 |
| 🇸🇰TildeOpen-SK 30B (Alpaca)(30B) | – | 32.77 | 57.45 | 34.17 | 33.61 | 13.31 | 27.19 | 30.90 |
| 🌐TildeOpen 30B-64k(30B) | – | 31.92 | 58.00 | 40.38 | 62.79 | 14.50 | 15.64 | 0.23 |
| 🌐Qwen3.5 2B(2B) | – | 29.43 | 43.38 | 34.16 | 56.91 | 11.18 | 18.81 | 12.16 |
| 🌐Nemotron 3 Nano 4B(4B) | – | 29.38 | 40.01 | 32.26 | 53.64 | 14.53 | 29.42 | 6.41 |
| 🌐Aya Expanse 8B(8B) | – | 28.58 | 44.53 | 25.80 | 58.96 | 12.34 | 15.08 | 14.75 |
| 🌐Qwen3 1.7B(1.7B) | – | 27.83 | 35.00 | 30.91 | 52.44 | 12.84 | 23.46 | 12.34 |
| 🌐Teuken 7B(7B) | – | 27.66 | 39.84 | 26.06 | 59.10 | 10.31 | 15.27 | 15.35 |
| 🌐Qwen3 0.6B(600M) | ✓ | 27.22 | 34.76 | 26.03 | 50.48 | 10.40 | 36.31 | 5.32 |
| 🌐Granite 4.0-H 1B(1B) | – | 25.63 | 39.81 | 28.22 | 50.07 | 14.82 | 14.90 | 5.98 |
| 🌐Llama 3.2 3B(3B) | – | 24.65 | 34.73 | 25.79 | 46.18 | 14.76 | 13.97 | 12.46 |
| 🌐Granite 3.2 2B(2B) | – | 24.41 | 38.23 | 22.47 | 51.70 | 8.66 | 13.78 | 11.62 |
| 🌐Qwen3.5 0.8B(800M) | – | 23.99 | 33.38 | 26.01 | 53.50 | 9.72 | 14.34 | 6.97 |
| 🌐Granite 4.0 1B(1B) | – | 23.25 | 34.48 | 27.60 | 41.85 | 13.20 | 17.13 | 5.24 |
| 🌐Gemma 3 1B(1B) | – | 22.75 | 35.12 | 19.85 | 54.38 | 11.83 | 12.29 | 3.01 |
| 🌐EuroLLM 1.7B(1.7B) | – | 21.87 | 35.16 | 19.20 | 40.30 | 13.43 | 14.71 | 8.40 |
| 🌐Qwen3 0.6B(600M) | – | 21.49 | 33.07 | 20.86 | 43.35 | 10.65 | 16.76 | 4.24 |
| 🌐Ministral 3 14B (R)(14B) | ✓ | 20.43 | 29.82 | 16.24 | 16.79 | 0.24 | 34.26 | 25.22 |
| 🌐Qwen3.5 2B(2B) | ✓ | 19.78 | 21.11 | 17.24 | 29.34 | 0.41 | 25.88 | 24.69 |
| 🇸🇰Mistral-SK 7B(7B) | – | 18.96 | 22.62 | 19.30 | 34.63 | 16.15 | 14.15 | 6.88 |
| 🌐TildeOpen 30B(30B) | – | 16.97 | 45.07 | 21.53 | 8.76 | 3.42 | 16.76 | 6.31 |
| 🌐Granite 4.0-H 350M(350M) | – | 15.07 | 25.46 | 9.37 | 27.30 | 11.69 | 15.27 | 1.31 |
| 🇸🇰Mistral-SK 7B (Alpaca)(7B) | – | 14.91 | 21.54 | 12.61 | 17.75 | 11.99 | 13.78 | 11.78 |
| 🌐Granite 4.0 350M(350M) | – | 12.28 | 27.53 | 10.10 | 13.78 | 9.73 | 10.80 | 1.77 |
| 🌐Qwen3.5 0.8B(800M) | ✓ | 7.19 | 2.29 | 1.02 | 4.56 | 0.28 | 24.39 | 10.60 |
Good to know
- Models are ranked by their overall score (Overall), which is the unweighted average of the scores of six task groups: knowledge & reasoning, reading comprehension & question answering, classification, generation, instruction following, and grammar & morphology. Each group score is the average of its task scores (× 100), with every task weighted equally. Each group uses its own metrics – for example, accuracy for multiple-choice questions or ROUGE-L for summarisation. Models that were also evaluated with thinking mode enabled appear in the table twice. A higher score means a better result.
- The results were published on SLAIH on October 6, 2026. Individual models may have been evaluated on different dates.
- A dash means the model has no result for that task. It is not a zero.
- If a model is missing from the table, no result for it is listed here. Its absence does not mean it performs worse.
- These results apply to this benchmark and its metric. They do not measure the model’s overall quality.
Datasets and methodology
Metric notes
- Overall
- The overall score is the unweighted average of the scores of the six task groups. Each group score is the average of its task scores (× 100), with every task weighted equally. This prevents large translated datasets from having a disproportionate influence on the overall result. A higher score means a better result.
- Knowledge & Reasoning
- Subject knowledge and common-sense reasoning, evaluated with multiple-choice questions: ARC-SK, Okapi-MMLU-SK, Global-MMLU-Lite, TruthfulQA-SK, Scio, Financial Exams, Autoškola, SlovakCOPA, SKJ1 and Slovak Trivia. Metric: accuracy, i.e. the share of correct answers.
- Reading & QA
- Reading comprehension and question answering: Belebele-SK, Chiby, MultiWikiQA-SK, e-testy-sk, Slovak-tests, OneRuler-SK and skLEP-QA. Multiple-choice tasks are scored by accuracy. Open-ended answers are scored with quasi-exact match (QEM) and quasi-F1 (QF1), which tolerate small differences in the wording of the answer.
- Classification
- Classification of sentences and documents: NLI-SK-annotated, skLEP-NLI/RTE/sentiment/hate, SentiSK, MovieReview and ToxicSK. Metric: accuracy, i.e. the share of correctly classified examples.
- Generation
- Text summarisation on the SlovakSum and SME-Sum datasets, with 1,500 examples sampled from each. Generated summaries are compared with a single human-written reference summary using ROUGE-L. The scores are therefore best read as a relative comparison of models, not as an absolute measure of summary quality.
- Instruction Following
- IFEval-SK evaluates how reliably models follow instructions whose fulfilment can be verified automatically. The checkers were adapted to Slovak, including the rules for word boundaries, capitalisation and punctuation. Metric: strict prompt-level accuracy, i.e. the share of prompts for which the model met all required conditions.
- Grammar & Morphology
- Generative tasks that test Slovak-specific language skills and cannot be created by simply translating existing datasets: Word Analogies, based on the Slovak Conceptual Dictionary, and Slohry, which tests word inflection. Metric: accuracy, i.e. the share of correct answers.
Info
- About sk-bench
- sk-bench is a benchmark that evaluates how well large language models handle Slovak. It includes 30 datasets from ten domains. It prioritises data originally created in Slovak and uses translations only where no Slovak alternative exists. Eleven resources are either entirely new or made available for the evaluation of generative language models for the first time. These include IFEval-SK, with checkers adapted to Slovak, as well as the native Slovak resources Chiby and SKJ1, which focus on grammar and morphology.
- Task groups in the results
- The results are divided into six groups by task type: knowledge & reasoning, reading comprehension & question answering, classification, text generation (summarisation), instruction following, and grammar & morphology. Each group score is the average of its task scores, with every task weighted equally. This prevents large translated datasets from having a disproportionate influence on the results. The overall score is the unweighted average of all six group scores, as in the GLUE and SuperGLUE benchmarks.
- Evaluation methodology
- All open- and closed-weight models are evaluated using the same procedure: the model generates an answer, which is then compared with the expected result. The evaluation is built on the LightEval library. Open-weight models are served with vLLM, while closed-weight models are accessed through LiteLLM. The same prompts, number of few-shot examples, token limits and scoring method apply to all models. The main results come from zero-shot evaluation with greedy decoding and Slovak instruction templates.
Key findings
- Open models trail proprietary ones
- The best open-weight model (MiniMax M3, 60.5 points) trails the best proprietary API model (Gemini 3.1 Pro, 72.6 points) by 12.1 points. Among open models, parameter count is only a weak predictor of performance in Slovak: for the strongest models, improvement largely levels off beyond approximately 20 billion parameters.
- Translation is a reliable proxy for native data in fixed-answer tasks
- On datasets with a fixed answer format, model rankings on native Slovak and translated data are almost identical (Spearman’s ρ ≥ 0.98 for NLI and multiple-choice questions). However, translated data is worse at distinguishing between the strongest models. Model rankings also differ between question-answering datasets written by humans and those generated by language models (ρ = 0.72).
- Reasoning mode helps in Slovak too
- Enabling reasoning mode raises the overall score of models with at least 9 billion parameters by 8.5 to 12.5 points, mainly thanks to better instruction following. The smallest models, however, are hurt by this mode, because they exhaust their token limit before producing an answer that can be evaluated.
Publications
- sk-bench: A Native-First Benchmark for Evaluating Large Language Models in Slovak (EMNLP 2026)
- sk-bench Leaderboard (Hugging Face Space)
- sk-bench – project page (GitHub Pages)
Use the results
Citation
When you use the results, cite the benchmark and its original publication.
sk-bench – a benchmark for evaluating generative language models (LLMs) in Slovak. SLAIH – Slovak Language AI Hub, October 6, 2026. https://slaih.sk/en/benchmarks/sk-bench
sk-bench: A Native-First Benchmark for Evaluating Large Language Models in Slovak. EMNLP 2026. https://aclanthology.org/2026.emnlp-main.2639/